What should a Data Scientist resume include?
A data scientist resume should include a short profile, a skills section with Python, SQL and your machine learning libraries, experience bullets that state the problem, model, metric and business result, one or two projects with GitHub links, and your education. Build it on FixDoks, keeping it to one or two pages and avoiding unexplained jargon.
Data Scientist Resume at a glance
| Design | Timeline, ATS-friendly |
|---|---|
| Sample | PDF and Word download |
| Examples | 14 bullet points, 23 skills |
| Processing | On our server over HTTPS; files are deleted right after conversion |
| Max file size | 50 MB per file |
| Price | Free to use, no watermark |
| Download | First download free, then ₹49 for 2 months of unlimited downloads (US$3 outside India) |
| Files at once | 1 free, up to 30 with a plan |
| Works on | Chrome, Edge, Safari and Firefox on Windows, Mac, Android and iPhone |
How to use Data Scientist Resume Template
- Click Use this template to open the builder with the Timeline design and a Data Scientist section order, or Edit this example to start from the sample.
- Fill in your details. Use Examples and Skills by job for ready-made lines, or the AI writer for your own notes.
- Check the resume score, paste the job ad to see missing keywords, then download your PDF.
Data Scientist resume sample
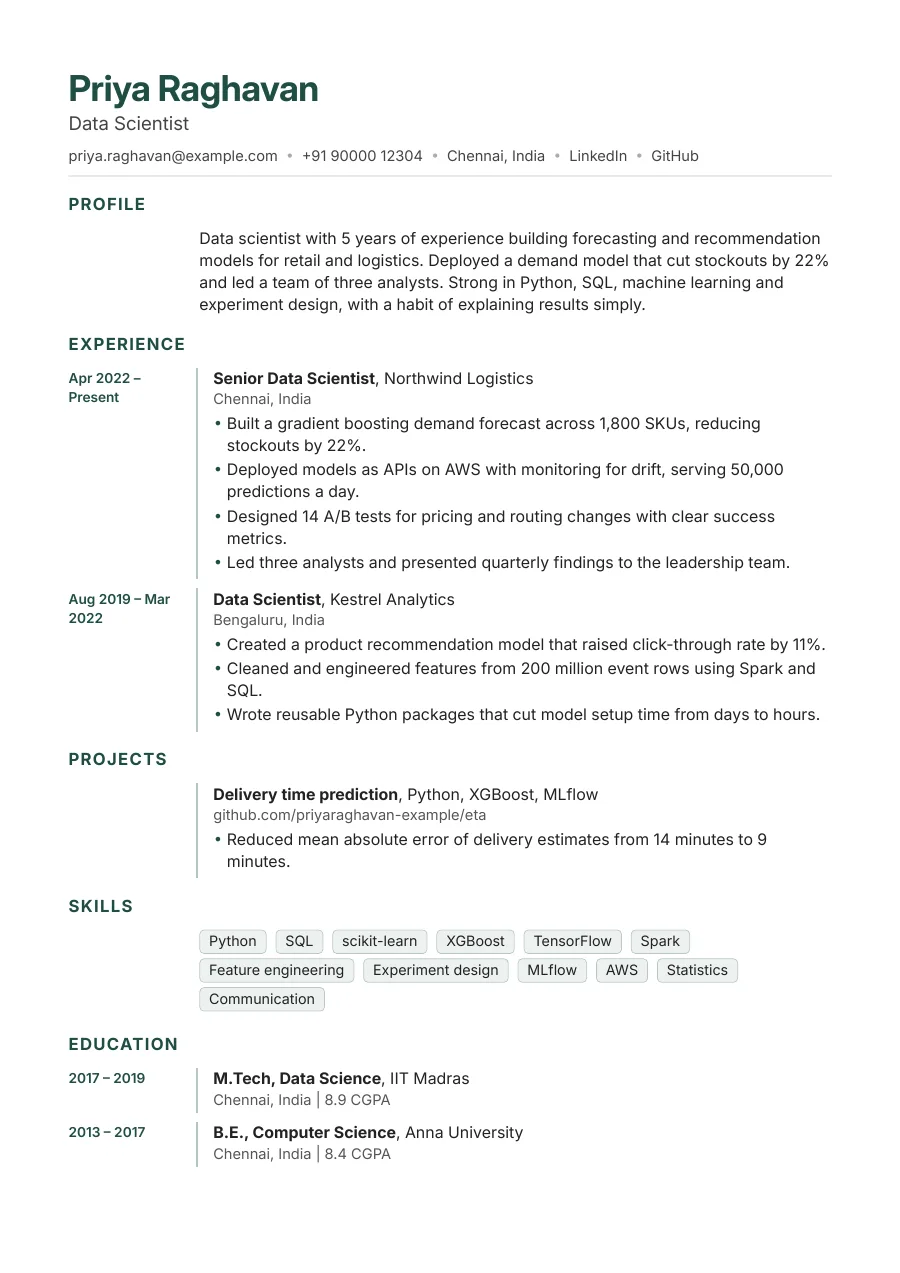
What recruiters look for in a data scientist
Hiring teams want proof that you can frame a business problem, build a sound model and get it used. A long list of algorithms does not help if no result follows. Your resume should show the problem, your approach, the metric you improved and the impact on the business or product.
Best section order
- Contact details with GitHub, LinkedIn and, if relevant, Kaggle or publications
- Profile of three lines
- Skills grouped by area
- Experience
- Projects or publications
- Education and certifications
Recent graduates and PhD holders can place education and research first. Everyone else leads with experience.
How to write the summary
Give years of experience, your domain, the type of models you build and one result. For example: five years in retail and logistics forecasting, deployed a demand model that cut stockouts by 22%. Skip vague phrases about being passionate about data. The summary generator can give you a draft.
Bullets that show impact
| Weak | Strong |
|---|---|
| Built machine learning models | Built a gradient boosting forecast across 1,800 SKUs, reducing stockouts by 22% |
| Worked on recommendations | Replaced rule-based suggestions with collaborative filtering, lifting click-through by 11% |
| Used Spark for big data | Engineered features from 200 million rows in Spark, cutting prep time from 6 hours to 50 minutes |
Always connect the model metric, such as error or AUC, with a business effect where you can. If the work is confidential, describe the scale and approach without naming customers.
Skills and ATS keywords
Match your wording to the posting. Common terms include:
- Languages and data: Python, R, SQL, Spark, pandas, NumPy
- Modelling: machine learning, deep learning, scikit-learn, XGBoost, TensorFlow, PyTorch, NLP, time series
- Method: statistics, hypothesis testing, A/B testing, feature engineering, cross-validation
- Production: MLflow, Docker, AWS, Azure, GCP, model monitoring, APIs
Check your text against a posting with the ATS resume checker.
Certifications and education
A master's degree in statistics, computer science or data science is common, but not required everywhere. Cloud credentials such as AWS Certified Machine Learning Specialty or the Azure Data Scientist Associate can show deployment skills. List publications and competition results only when they are relevant.
Publications and competitions
Add a short section only if the items are relevant: peer reviewed papers, a Kaggle medal, or a talk at a known conference. Give the title, venue and year. If they are unrelated to the job, leave them off and use the space for another bullet about production work.
India and abroad notes
- India: include degree, institute and CGPA for the first few years. Photo is optional.
- US, UK, Europe: leave out photo and date of birth. For research roles a two page CV with publications is acceptable. Mention work authorisation when asked.
Tailoring and format
Data science postings differ widely. Some want analytics and experimentation, others want production machine learning or research. Read the posting, decide which type it is, and reorder your bullets so the closest match appears first. Use one column, a standard font and a PDF export. Put a GitHub link near your name and check that the top repositories have clear descriptions. Keep technical terms in plain text rather than in images or charts.
Common mistakes
- Listing every algorithm instead of what you shipped
- Reporting accuracy alone, with no baseline or business effect
- Notebook projects with no explanation of data, method or limits
- Overusing buzzwords like AI-driven or cutting-edge
- No link to code or a write-up
Start from one of the resume templates, then tailor your bullets to each posting.
Skills for a Data Scientist resume
Pick the ones that are true for you and that the job ad mentions. In the builder, Skills by job adds them with one tap.
- Python
- SQL
- Machine learning
- Deep learning
- scikit-learn
- XGBoost
- TensorFlow
- PyTorch
- Spark
- Feature engineering
- Statistics
- Experiment design
- A/B testing
- Time series forecasting
- NLP
- MLflow
- AWS
- Docker
- Git
- Data storytelling
- Problem solving
- Stakeholder management
- Mentoring
Data Scientist resume bullet point examples
Use these as a starting point and change the numbers and details to your own. Anything in [brackets] is a placeholder for your real figure.
- Built a gradient boosting demand forecast across 1,800 SKUs that reduced stockouts by 22% within two quarters.
- Deployed a recommendation model as an API on AWS, serving 50,000 predictions a day with drift monitoring.
- Raised click-through rate by 11% by replacing rule-based suggestions with a collaborative filtering model.
- Engineered features from 200 million event rows using Spark and SQL, shortening training data preparation from 6 hours to 50 minutes.
- Designed and analysed 14 A/B tests on pricing and routing, three of which were rolled out company wide.
- Reduced delivery time prediction error from 14 minutes to 9 minutes by adding traffic and weather features.
- Led a team of three analysts, setting model review standards and cutting rework on submitted analyses by half.
- Packaged reusable Python modules for preprocessing and evaluation, cutting new project setup time from days to hours.
- Presented model findings to executives each quarter, translating accuracy metrics into revenue and cost impact.
- Built an NLP classifier that tagged support tickets with 91% accuracy, saving agents about [X hours] a week.
- Detected and corrected data leakage in an existing churn model, restoring realistic performance expectations for [X teams].
- Tracked experiments and model versions in MLflow so [X data scientists] could reproduce each other's results.
- Reduced cloud training costs by [X%] by switching to spot instances and early stopping.
- Mentored [X junior analysts] on model validation, cross-validation and clear communication of uncertainty to stakeholders.
Resume summary examples for a Data Scientist
Data scientist with 5 years of experience in forecasting and recommendation systems. Takes models from notebook to production on AWS and measures them against business goals. Clear communicator who explains accuracy, risk and trade-offs to non-technical teams, and who documents experiments so colleagues can reproduce and extend them.
Senior data scientist leading a small team in logistics analytics. Deep experience in time series, experiment design and feature engineering at large scale, with a record of mentoring analysts. Looking to own end to end machine learning products in a larger organisation with real users.
Data scientist with an M.Tech and 3 years of experience in NLP and classification. Built models that save support teams hours each week. Comfortable with PyTorch, Spark and MLflow, and interested in applied research with real users, where careful evaluation matters as much as model accuracy.
More resume examples
- Cybersecurity Analyst resume
- Data Analyst resume
- DevOps Engineer resume
- Frontend Developer resume
- IT Support Engineer resume
- QA Tester resume
- Accountant resume
- Architect resume
- All resume examples by profession